

Many thanks to the members of the More Than Moore team who contributed to this project: Dustin Sklavos, Justin Cutress, and Domenico Lamberti. Also thank you to Richard and his team at OpenAI for making time for us.
In June 2026, OpenAI confirmed what the industry had assumed for a year - that it was building its own silicon with Broadcom as design partner and Celestica handling board and rack integration. The part is called Jalapeño. Since then we’ve had more details come to light.
It is an inference accelerator rather than a training chip, and it carries 216 GiB of HBM4 at 15.4 TB/s alongside a compute die and an IO chiplet. Chip power is rated at 700 W peak with measured sustained draw closer to 550 W. A local domain is 128 accelerators, a full system is 2,048 accelerators, and at four-bit precision that system reaches 27 EFLOP/s.
At HotChips 2026, Richard Ho presented the first measured performance from working silicon, alongside Ravi Narayanaswami and Chris Leary. The numbers claimed against NVIDIA GB200/GB300:
1.5x to 1.9x better performance per watt at peak throughput
1.7x to 3.6x better latency
Up to 104x better at operating points NVIDIA struggles to reach.

Richard Ho at HotChips 2026
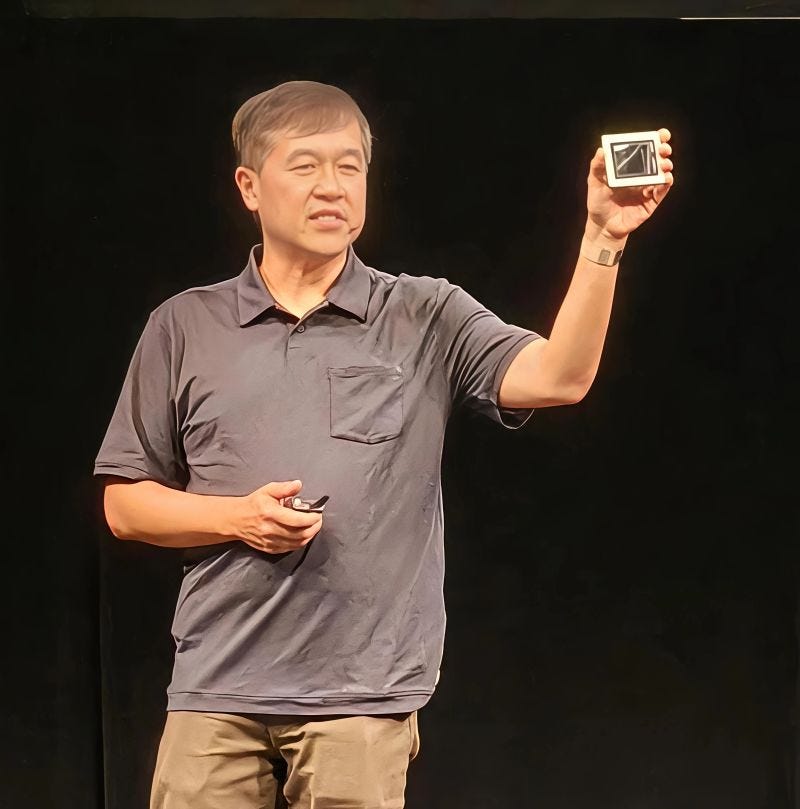
Two things about that talk drew attention. The first is that OpenAI built a single balanced part for the entire inference workload. Today we’re seeing hardware vendors splitting the workload between prefill, speculative decode, and full decode, across specialised hardware for each. This means Jalapeno is designed to be a homogenous datacenter integration, contrary to the rest of the market.
The second is how much of the chip was designed with help from OpenAI’s own models. This includes compute design, fitting circuits into the available area, and then post optimizing kernels for the hardware. One attention implementation went from under one percent of the memory/compute roofline to nearly ninety percent in roughly forty hours.
Richard is not new to any of this. In his past, he has built verification tooling, co-founded an EDA company, worked on the Anton supercomputers at D. E. Shaw Research, and was among the first engineers on Google’s TPU programme, through which he was a part for seven or eight generations. He then spent a brief stint in optical interconnect, before joining OpenAI in 2023 as one of the first team members for its hardware project.
In this interview, the conversation runs from that history, through the architecture, the benchmark choices, the partnership with Broadcom, the memory supply question, and where he thinks the industry’s real constraint sits. It was recorded in OpenAI’s own studio.
You can either watch the recording, or read the transcript underneath.
The following transcript has been lightly edited for clarity. If you enjoy this work, please consider subscribing to More Than Moore. We aim to ensure that content is free at the point of publication, and subscribing helps that goal!
Ian Cutress: With a wild and varied background in chip design, how did you get here?
Richard Ho: I started way, way back when the original kind of multi-processors were starting at Stanford, and John Hennessy of RISC fame and SGI fame - he was running a big multi-node computer project at Stanford. I was the most junior engineer on there. And at that time, here are all these PhD students who are doing a thesis and stuff like that, and I started in verification. I did that, I did my PhD in verification, and I did an EDA startup on verification.
But my heart was always in supercomputing design. So the moment I was able to, the moment I got that company acquired, I jumped back into supercomputing design, and went over to D.E. Shaw Research. David Shaw is a very wealthy hedge fund guy who decided to put his money to good use. He wanted to build supercomputers for drug discovery. I think his goal was ultimately to try to help in the cure for cancer, to somehow find it. And we built some pretty amazing supercomputers there: Anton 1, Anton 2, Anton 3. They’re actually the precursors in many ways of the Google’s TPU AI accelerator. So a lot of the kind of supercomputing, dedicated ASICs, the networking, all of that stuff came from there.
And I spent a good number of years there. I luckily got to Google, to work on the TPU as one of their first engineers. To be honest with you, they came to me and I said, “What are we working on? What is this for?” They said, “We can’t tell you.” It was a secret, right? And they said, “But you won’t regret it. You’ll enjoy it.”
Ian Cutress: So this is like Bletchley Park. We have to hire you, but we won’t tell you what you’re working on!
Richard Ho: Exactly. I jumped on board and then I found out. Jeff Dean said we needed acceleration because Translate is using too much of the compute power in the computer centers. We needed to have a specialized piece of hardware to do that, and I was part of the team to do it.
Ian Cutress: But this was still from the HPC perspective?
Richard Ho: It was the HPC translation, but we were doing a specific accelerator just for the inference part of the translation there. So it was very dedicated. At that time it was convolutional neural networks - it wasn’t anything to do with LLMs, it was just writing convolutional neural networks to take a word in one language and put out the right word in the other language, so that’s what we did. We built up a nice program there, we did seven or eight different generations of TPUs, learned a lot along the way, not only about what it takes to do ML acceleration, but also how to build a chip with a small team, and that’s where it started.
Ian Cutress: Roughly what size was the team?
Richard Ho: A lot of the TPUs were built with a team that’s in the order of 300 people there, and it was a very similar structure in the sense that the front-end design was done by the team and then gates were handed off to our ASIC partner. They do the back-end design, and then from there, I did many generations. I got to the stage where I thought about what was next in ML acceleration - I looked around and realised we need to do something about communication. I jumped over to a startup company (Lightmatter) that was doing silicon photonics for communication. I thought that was going to be the next big thing, and I still think it will be.
But then OpenAI called, and they told me they were inching into hardware. I thought to myself that it was interesting, that they want to do hardware. So I went to talk to them about it.
I managed to talk with Sam Altman and he was super excited about hardware. He was super keen on hardware for many, many years. Doesn’t matter if it was chips, hardware, fabs - it was everything, everything, everything. He was quite the visionary. So when they asked I said for sure I was coming aboard.
You’ll have to characterize it like the Ocean’s 11 thing where I just went around to all my old buddies like, “Hey, you want to go for this ride? It could be fun here, right?” We basically pulled the old team together back here, and we’ve been partying and rocking for a couple of years now.
Ian Cutress: So the D.E. Shaw team has done a route?
Richard Ho: It’s not all D.E. Shaw, a lot of it is Google, and we have people from Meta and Amazon and other places. Obviously, talent is spread throughout. One of the things I would say is we have been very fortunate. I think because OpenAI is kind of a frontier lab, it’s exciting. We’ve had very good fortune in attracting some of the best talent in the industry to come here and do this.
Ian Cutress: It’s in your blood. But you founded a verification startup when you were very young in terms of your career. Do you think that helped or hindered? Does it make you more paranoid?
Richard Ho: I think it does. I don’t need the paranoid side, but it gives you the perspective on two things.
One, I think it gives you the perspective of engineering for the customer and what the customer needs in the product. I think that was a really strong learning experience.
And the second thing I learned was that you really have to take what you think you know works and break it apart, and try to do something different, and not accept what is kind of mainstream thinking. We took the problem back to the bare bones and thought about it again - if there was a better way to do it than what has been done for the last ten years.
Being a co-founder of a startup company, you always do that, and kudos to everyone who’s ever tried that. It’s a major, major effort - that’s a lot of stress and a lot of work. But it teaches you a lot. And I think that really has helped a lot in my later career where those kind of learnings and steps really play parts in the way we make decisions, the way we approach talent, the way we think about how to solve a problem and how to evaluate it. And to be honest, to take the big bets.
Ian Cutress: That was going to be my next question. You’ve gone hardware, hardware, hardware, and then suddenly you’ve gone to a model company. What convinced you that they were going to give you enough rope to do what you wanted?
Richard Ho: It is a bet. It is a bet. I mean, I think a lot of the people that I hired did ask that question. They asked if the team was committed, if OpenAI was committed. They didn’t want to do a science project and then have to go find something else. But it is a bet, and I think what it boiled down to for me was the one-on-one conversation with Sam Altman. I could see that he was committed to do this.
One of the interesting things I always reflect back on is in my first few months here, he and I and a few other people on a tour of Asia. We visited TSMC, all the memory companies, stuff like that. He already laid out this vision for the people and said that we need to build more fabs. This was two plus years ago.
Ian Cutress: I remember the talk with Pat Gelsinger later at Intel Foundry Direct Connect, he was saying that.
Richard Ho: Exactly. He was talking about that. And he was saying the AI factories, that we have to have more tokens, and I could just see that he was a visionary. It’s actually interesting to reflect back now with the wafer constraints that we’re under, the memory constraints we’re under, but he was dead on. I mean, the manufacturers did respond to that, but not enough. They didn’t respond to the level he wanted.
Ian Cutress: We can argue that certain parts of the industry have to deal with booms and busts so putting $100 billion in without knowing where it’s going can be a concern.
Ian Cutress: But in terms of building the team here at OpenAI, the way you’ve laid it out - it’s still not clear whether it was the idea-first or team-first?
Richard Ho: Team first. We all came onboard, and the first thing we did was to evaluate what the models did and how the models worked. But to do that, you have to have a good team, you have to have people who are able to understand it. You have to have people who have the same kind of founder mindset: to take ownership of the problem, be creative. That includes not taking prior art as being the only way to do it, and break it apart.
I think that the first few hires were the most important. The first few are the people who you can brainstorm with, you can reflect ideas off and bounce things off. So it really felt like a startup company inside a startup company. That’s kind of the way we operate it.
So it was people first. The idea of what to do came a little later, and that was from an understanding of the workloads. We had the privilege, and I think I’ve said this in a few places, but we had the privilege of having a blank slate, meaning that we did not have to look at legacy, did not have that backwards order thing, so we were able to say look at the crazy ideas. We actually did some of the crazy ideas. If you actually go look, there are some patents that are now published that we were thinking about back then. Some of them are pretty crazy. We didn’t go down those paths, but we thought about them and we thought about a lot of different things, and then we decided we do some stuff and put it out there.
Ian Cutress: Were there any pitfalls you identified early that you tried to get the team here to avoid?
Ian Cutress: You’re saying you’re doing clean sheet design - was there something that you couldn’t necessarily do while you were at Google because you had to have that legacy? Everybody’s got blind spots. And if you hire, I’m not saying your friends, but the expertise, there’s a chance they’ll just do the same thing again.
Richard Ho: I think the biggest pitfall that we were wary of was that the models we knew were changing quite rapidly. I think that was the thing that we were most worried about. One of the lessons that we had learned from doing the TPU stuff was that you have to make it programmable. But it’s not like you don’t burn everything into silicon because that narrows down your ability.
There are limitations to it. As long as they’re limitations you’re willing to deliver, they’re good. But if you’re able to make it programmable, then you have a lot of flexibility in adapting to change, and we had to adapt to change. TPU also adapted to different changes in the algorithm, even at that time on CNN stuff. And clearly now in the world of LLMs and the world of agents, stuff like that, the mix of stuff is changing pretty rapidly. And so that was the one pitfall that we really wanted to avoid, was to over design and over fit to one particular model. So we looked at it in that context.
Ian Cutress: Time to market is also a key constraint when you’re thinking about it.
Richard Ho: So that’s the other thing. It was interesting, I was reflecting back on some of our early slides we were presenting. One of the things we identified really early was execution speed really mattered. You have to get the hardware out as fast as you can because models change and you want to try to minimize that gap as much as you can. That’s the reason why my team has been working really hard with the AI models.
Ian Cutress: If you’re building a hardware team here, you can’t just ignore the fact that the company is a software company. Even if you’re building a hardware team, what was your interaction with the software team at that point? Did they perceive you as trying to change how it all worked?
Richard Ho: No, but as I was coming in, I was actually talking with the existing software people who were here to see how excited they were to do this. I was asking if they were excited to try new things, or if they were happy with the status quo.
Ian Cutress: [jokingly] As in “We’re happy with 5% gains per year.”!
Richard Ho: Exactly! And that’s the nice thing. I think there was excitement about trying to do better and a desire to do better.
In that process when we were arriving and figuring out what we wanted to do, the primary stakeholder we wanted to get aligned with what we were thinking of doing was the software team. The compiler team, the kernel optimization team, the inference team, all those people had to be excited about what we were proposing before we went to go and do it.
So a lot of the work was spent showing them. Things like building a very accurate but fast simulator, and then showing them this is what we could do. We asked them what they thought about it, if they’d be able to make use of it. We got really good support, really good enthusiasm, and that helped decide where we focused.
That’s step one. That is absolutely step one. It’s not just landing on an architecture and having a go, software has to come along and conclude that we can make this work together.
Ian Cutress: A few steps further down the line is about how do you optimize software for the hardware, and the hardware for the software, making sure you don’t hit that valley of misoptimization.
Richard Ho: Exactly. That’s an ongoing process, and everyone now says that. But living it, it’s harder, because it is, in a sense, organizational related. Typically in a lot of companies, the software team and the hardware team are different teams and different orgs. Different floors, different buildings, and they may only meet up at like the COO or CTO level.
Ian Cutress: It’s like you’re saying this from experience!
Richard Ho: [laughing] Not saying anything explicitly! But here at OpenAI, one of the early decisions that we made that was really valuable was that the hardware team sits with the research team. We’re in the same tent. We’re all together, we share the information, we’re in the same meetings. We can go to the research meeting, we see what research is going on, we see the results that are going on. And we’re able to talk with them in the lunchroom, in the cafe, at the break room, and stuff like that.
I think that was a real key secret sauce of what made this work - that deep personal interconnection. Not org level connection, one-on-one personal connection. People know each other, and they’re bouncing ideas off each other in a Slack in the middle of the night, stuff like that. I think that’s really important.
Ian Cutress: Normally when I deal with startups who are also trying to make AI hardware, half the discussions I have with them are about fundraising. How hard did you have to fight internally for budget? It’s very hard to place how much you guys spend on a chip versus somebody else.
Richard Ho: I would say that in our prior companies, that was really one of the challenges. One of the joys of OpenAI is if the founder and CEO wants to make this happen.
Ian Cutress: Blank check?
Richard Ho: It’s not a black check, but it’s pretty close. We want to be very diligent and careful with our resources. And on the flip side of that, I think a small team runs faster than a big team. There’s more interconnectivity. There’s people who understand each other, can chat with each other and know what’s going on. And so we try to keep it small, but essentially it was about doing what you need to do to make this thing good and happen fast. I think that was really a joy, to have that level of freedom in an organization.
Ian Cutress: If this had happened, say, two years earlier, what do you think would have changed?
Richard Ho: It was kind of the timing and everything worked perfectly. So if you say two years earlier, that was kind of pre-ChatGPT era. ChatGPT was announced in 2022 and I got hired in 2023. I think that things might have been very different, like the type of acceleration that we would have focused on. Your blank slate design would have gone off in a different direction, so there’s a lot to be said there.
The other thing I think is interesting, is that the timing of it was when the reasoning team started coming on board. That was when the analysis model, the thinking, and the change of thoughts and stuff, there was confidence it was actually going to work out. And that fed into thinking of how the architecture would look and what it would want to focus on and how important inference would become in the reinforcement learning loop and stuff like that. So it was becoming pretty clear that was where we had to focus our efforts.
Ian Cutress: Around that time, I think Synopsys announced their first AI EDA tool as well. You’ve leveraged quite heavily in your announcements with the Jalapeño chip that you’re extensively using machine learning to help design it. What exactly did you do?
Richard Ho: So in my team, we’ve always tried to use automation for a start and AI where we could. Even in prior jobs, we did that. But coming over here and having access to the models and researchers, I think opened up a kind of a set of tools that we didn’t have access to before.
What we found is, because we’re trying to go fast on the execution, we ran into some real problems. We ran into the problem of going after performance targets that we were promising based on the simulation, based on our estimates of what logic we could fit within our area, and it turned out it was a little bit off and you can’t quite fit it in there. You have to ask if you going to take that performance hit here or not.
We turned to the models and went to optimization. Solve for X. And it was actually surprisingly good. In one example we saved over 13% die area.
Ian Cutress: Are these raw models, or ones that you’ve fine-tuned?
Richard Ho: No, no, no. They were not fine-tuned at all! Just the raw models. A lot of them were internal models, so they’re a little bit ahead of the public models. They’re a little bit more capable, but not that much more capable. Recent models have even better stuff. But at that time, it was not a fine-tuned model. In fact, at that time, we were actually scrambling, we were looking around for more hardware repos that we could feed in for data. There was not much quality data at that time.
Ian Cutress: That sounds like the argument that the EDA vendors have. They’ve got 30 years of partner data, not all of it complete, and that’s still not enough for them.
Ian Cutress: But in terms of using your own models versus using the EDA partners’ models, was there a bit of back and forth?
Richard Ho: So I think our foundational model is very strong. I think the EDA companies, they’re developing frameworks around models. I think our internal model was a lot stronger at doing this stuff than theirs. It’s a research problem, so we had the ML researchers helping us figure out how to get the best results, and they were able to do something really amazing for us.
Ian Cutress: What do you think the biggest benefit of using the tools was? Was it simply time to market or actually hitting the performance goals?
Richard Ho: Well, those two things are related. It was time to market at the performance goal. Otherwise, we would have to trade one or the other.
Ian Cutress: Or use humans?
Richard Ho: Even using humans, you would have the trade-off. Even using humans, I think we would have to either have a longer development cycle or lower performance. These are good engineers, right? It’s just a hard problem. I think the models, when I try to conceptualize why they were successful, I think they get a big view of everything. They’re actually able to kind of reason about different aspects of it and figure out exactly where there are some soft spots in the design where you can shift stuff around.
It doesn’t fit in the brain very easily. Or at least most brains. So I think that’s what I kind of visualize, what’s going on. Why are the models so good at this? That’s one of the things I figured out, that they’re just very systematic and they’re able to hold a lot together in their context window and think about it and figure it out. A human has a lot of difficulty trying to piece together what’s going on in this part of the design, what’s going on in that piece of the design, how does it correlate and where do I merge it? And to do that end-to-end across a whole chip, that’s challenging. I think that’s where the models have started.
Ian Cutress: Is there something the models can’t do?
Richard Ho: Well, I still don’t 100% trust them. So, for example, one person asked me, would these models replace EDA tools? I don’t think so in the near term. We still use standard EDA flows to sign off. If you have a 300 million gate design or whatever number of gates it is, If the model is 99.99% correct, you can’t tape that out, it’s not accurate enough!
But the way we’re thinking about it is that the models turn our engineers into super engineers. They’re super charging engineers, but the engineers are still responsible for what actually is going in and how they are actually going to do this.
Ian Cutress: So are you an advocate for enabling engineers to do more or having fewer engineers? Because of what you said about having a smaller team.
Richard Ho: I do believe in smaller teams, but that was even before the models were coming in. But I think now, would I reduce this team? I would hesitate to. I would say do more, do it better, do it faster with the models. That’s the way I would do it.
Ian Cutress: As engineers, I find that a lot of us, we want to know everything that’s going on line by line, code by code. If we’re reading a book, we want to understand every page. The fact that these AI models are coming up with answers that may not be necessarily obvious as to how they’ve solved it, does that worry you?
Richard Ho: Yes, it does. Actually, there’s a specific example. When we had the optimizations, the source code optimizations that the models did, and we initially did not understand exactly why they were doing it. We didn’t quite understand conceptually what it was doing. We said we would probably get there, we’d need to spend some time to think about it. But we were running fast, so we weren’t able to spend the time to understand.
Yeah, it is a little bit worrying. We don’t exactly know what it is, that’s why we do need to have the full validation flow following that to make sure that nothing else was broken. I think you always have to do that. In the context of chip design, those are the guardrails that you have, you need to have those guardrails. It does worry me, but as long as we are cognizant of that risk and we’re approaching it cautiously and deliberately, I think it’s a good risk to take.
Ian Cutress: Was there anything you found that worked in FPGA in simulation but didn’t work in silicon? Were your models aligned?
Richard Ho: They were quite aligned, they were correlated as well. We actually spent some time correlating them. The only place I think there’s any risk is on analog stuff. That’s the one that’s always tough.
Ian Cutress: I’m convinced analog is a form of magic. You need to be a wizard.
Richard Ho: Yeah, exactly! The signal integrity and that stuff. That’s the only one where we weren’t sure it was going to work. We build it in and we validate it.
Ian Cutress: Well, I guess you use your partner Broadcom for a lot of that. They’re the experts in the field.
Richard Ho: But even then, I think any time a new piece of analog comes in, it’s a little knock on wood.
Ian Cutress: I had a question from the audience: To what extent did you use XLS?
Richard Ho: Oh yeah, a lot. So XLS is Accelerated Hardware Synthesis. It is a high-level synthesis tool. It was actually written by a member of the team, Chris Leary, who open-sourced it when we were at Google. The reason why XLS is really helpful - and it really got us off the ground here - is because its syntax and semantics are based more on Rust as a software programming language and programming paradigm.
And what we found was that, one, it made it easier for non-hardware RTL people to understand what was going on. So that was good just for engineering team. But two, it really accelerated the models because they didn’t fully understand Verilog. At the time, they didn’t understand system Verilog. But they did understand software, so they were able to reason about it. The parts that we had done this optimization on were mostly XLS code, actually, making it able to understand the semantics of the language and do the right things as opposed to being in Verilog. Until recently, I think a lot of models still struggled with Verilog a little bit.
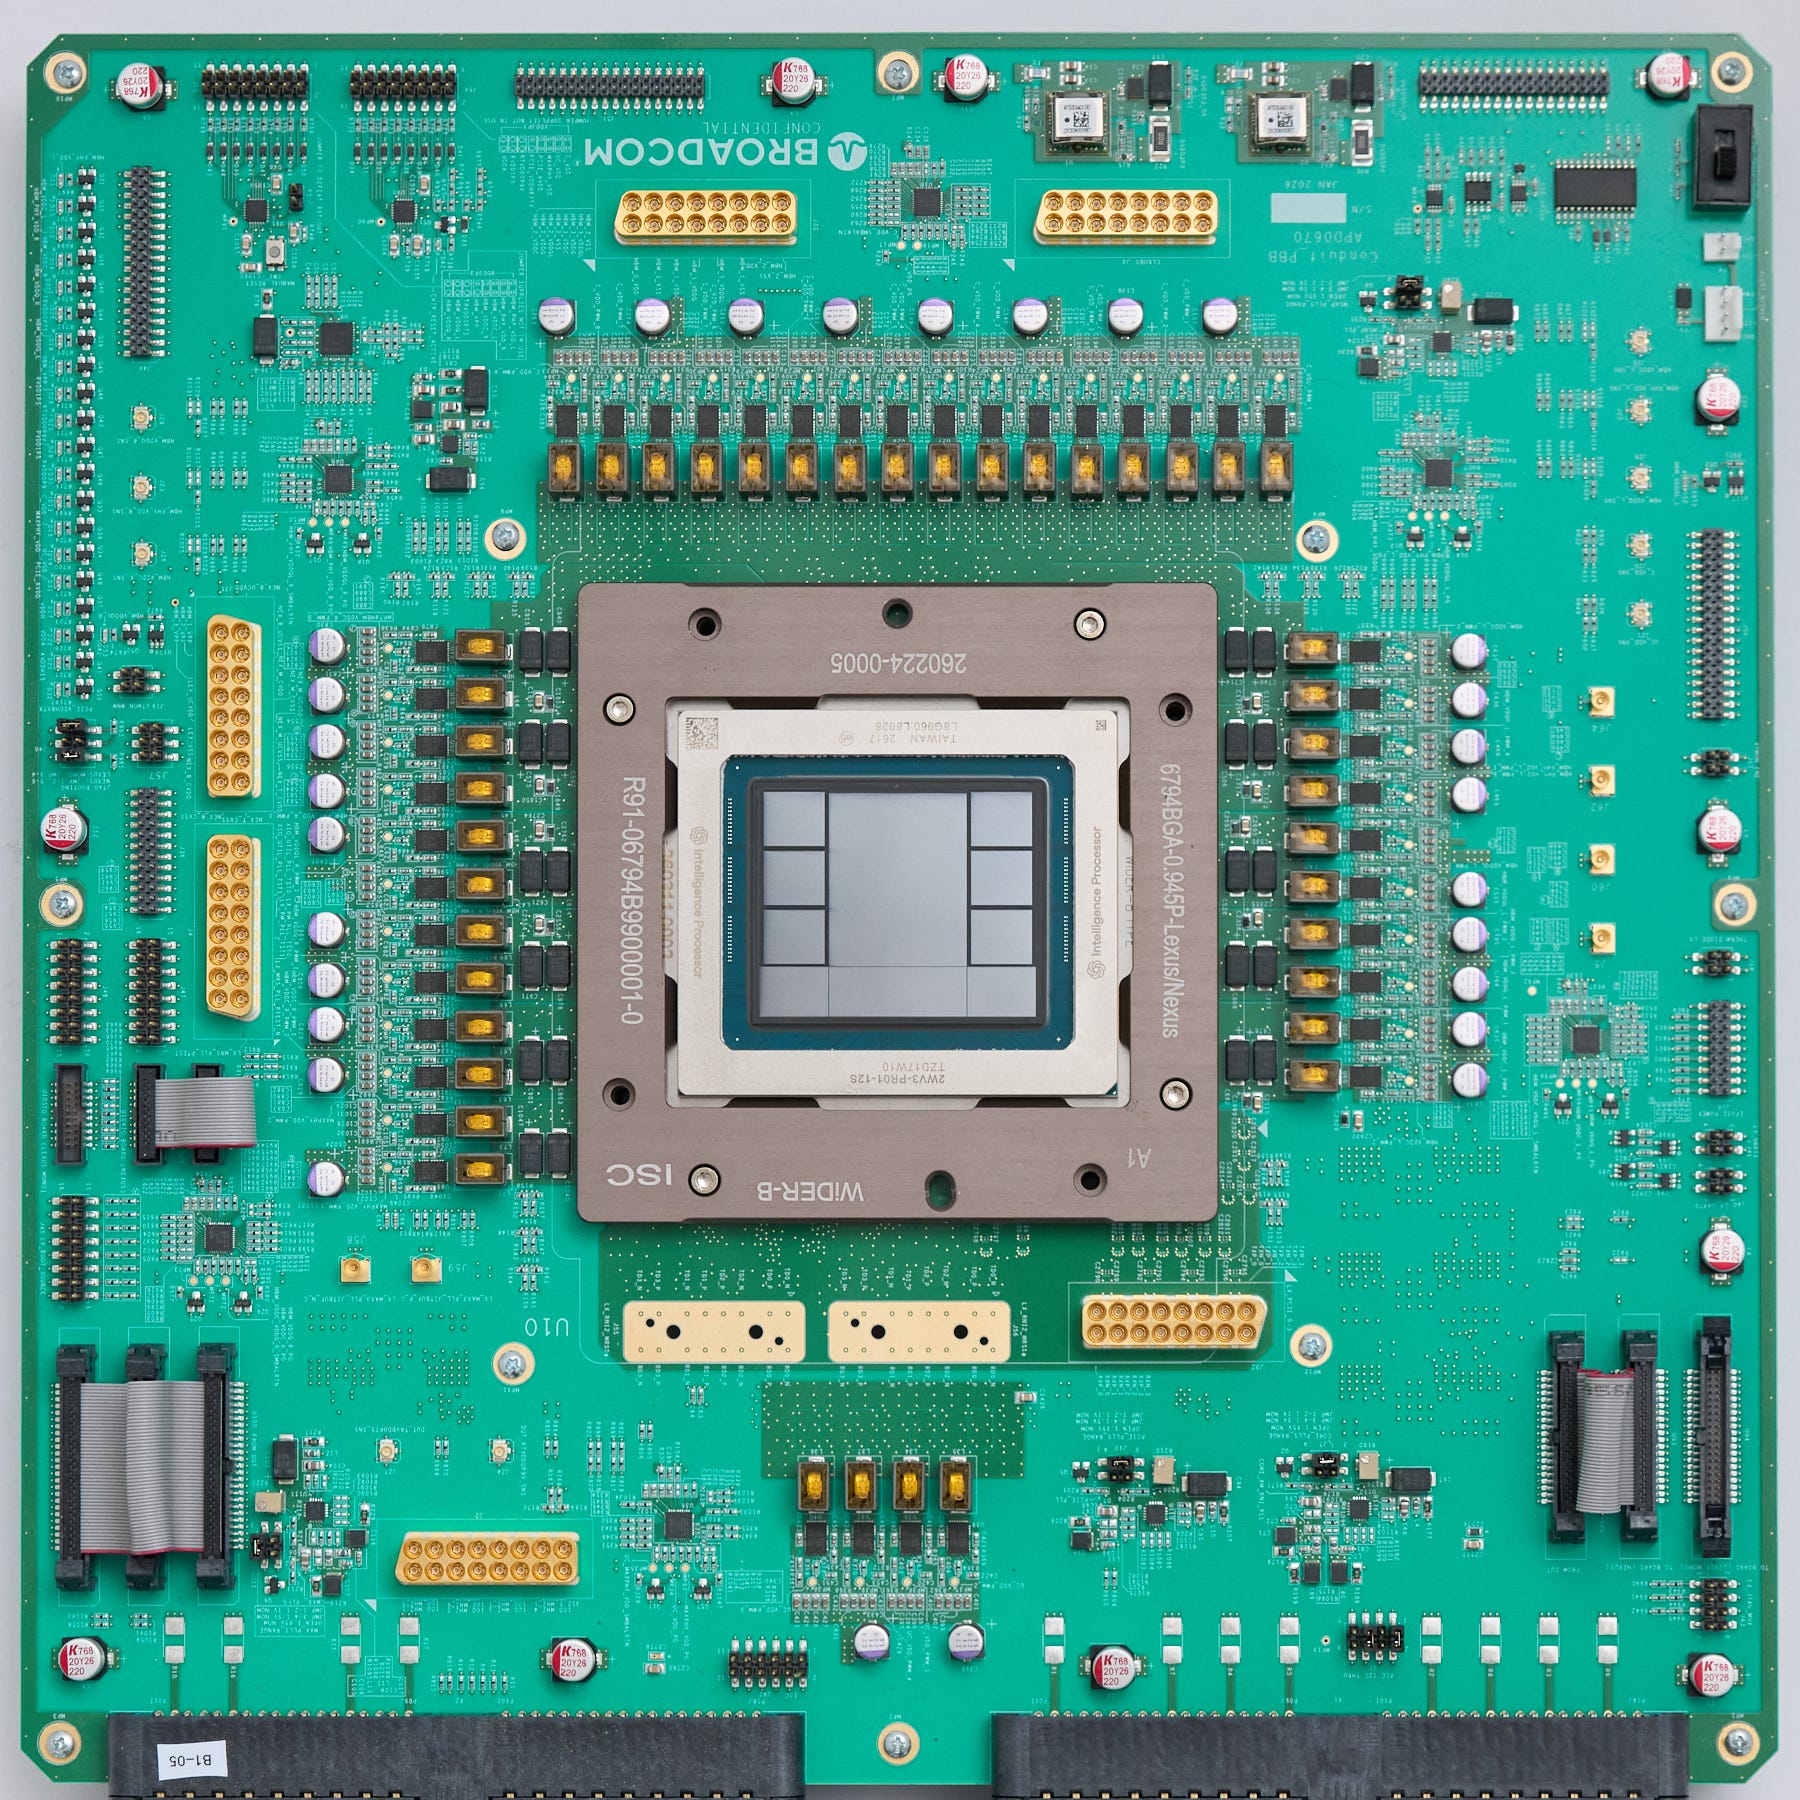
Ian Cutress: Was Jalapeño the first chip, or did you get a chance to do a test chip?
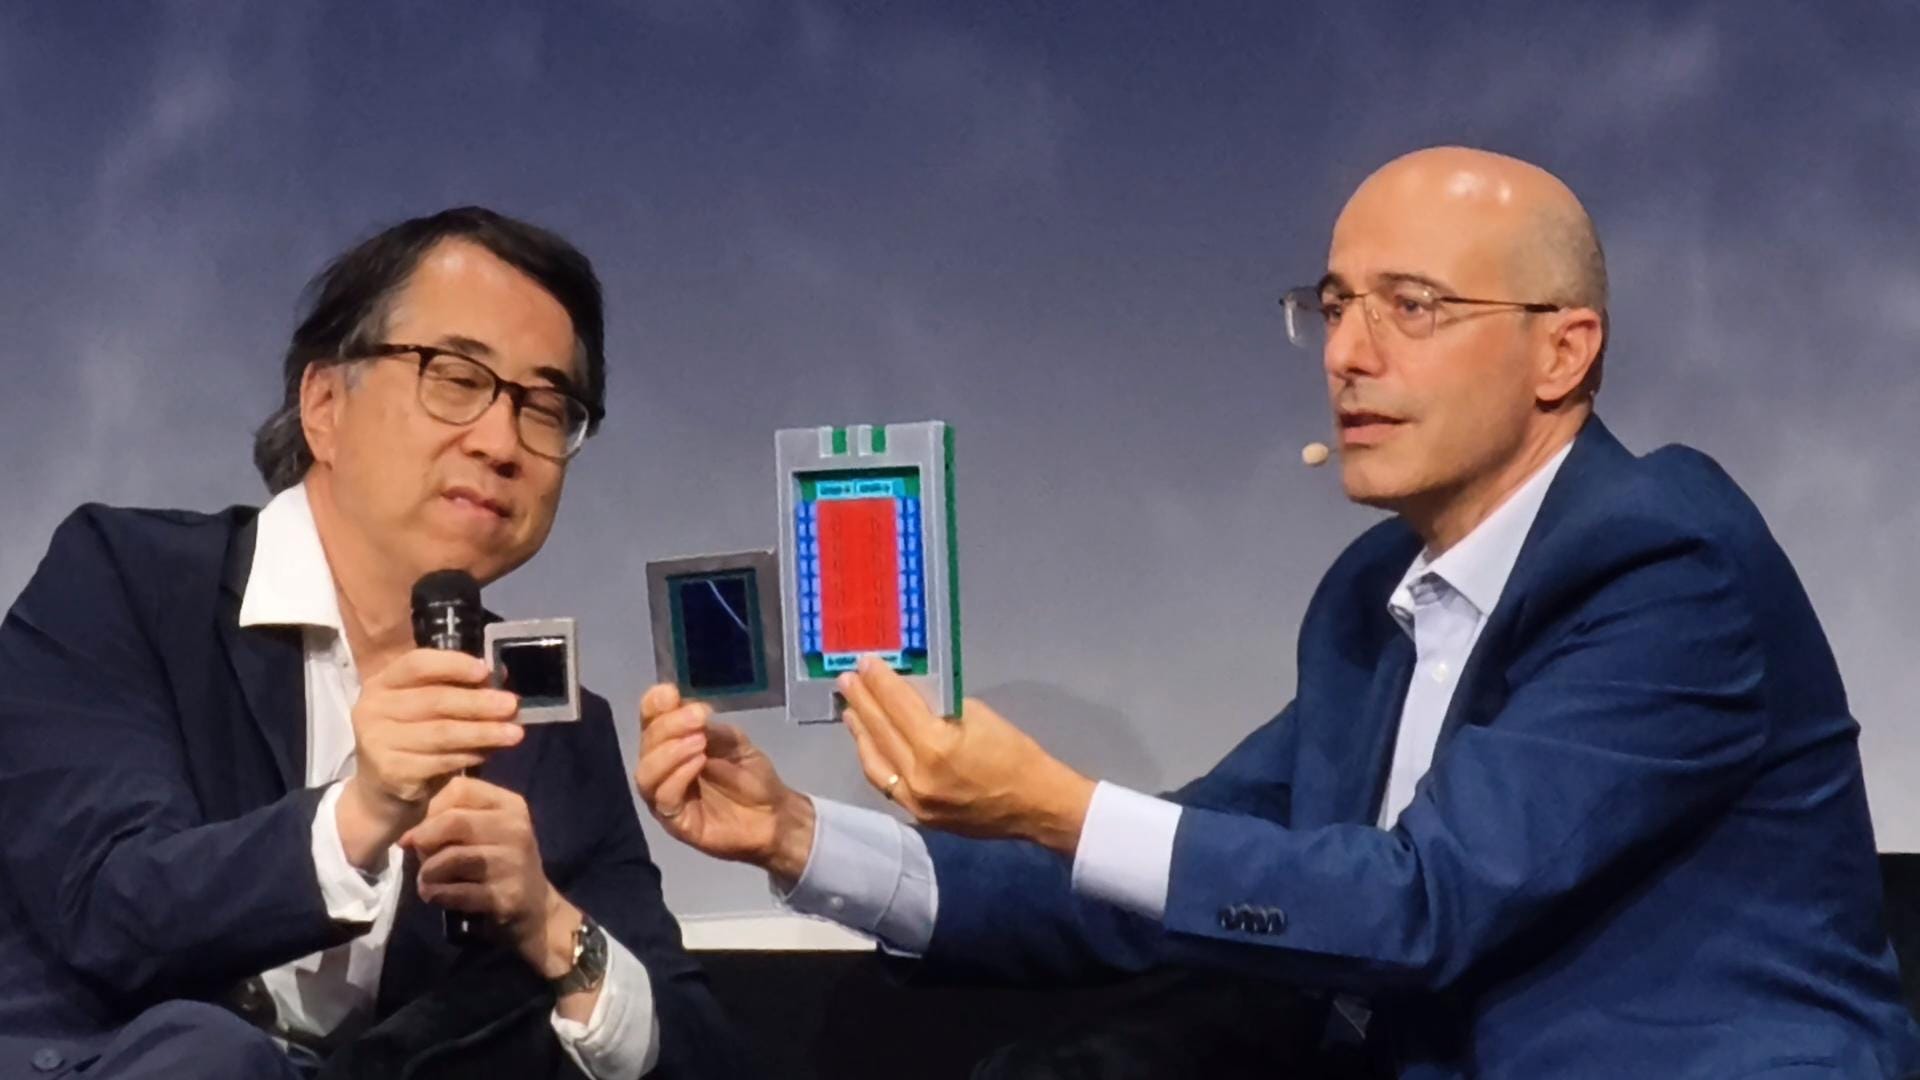
Richard Ho: Technically it’s a first chip, but if look at the photograph, you’ll notice the HBMs, right? You’ll notice the compute die, and there’s the I/O chiplet. The I/O chiplet came first. Once it arrived, we had a very accelerated schedule. So we did as much as we could, as early as we could, even if it’s with partial components.
Ian Cutress: Is that what they call “shift left?”
Richard Ho: Yeah, something like that. We did a lot of shifting left so we were able to bring up more components. The other thing we talked about was doing an A0-B0 stepping, and that was intentional. It’s not like we found something wrong in A0, and then we did a B0; we actually had that plan from the start. And that was, again, shifting left because we were going fast to bring up the system. We brought up the software and A0 had all the features we needed for performance and everything else while we were finishing off the design. Now the B0 is in the lab and going through all the qualification right now.
Ian Cutress: If you were looking at somebody else’s AI-based chip design tools, what are the key indicators that you would need from those tools to convince you that they’re worth using? Is there a risk that being at OpenAI of not having a wide enough vision?
Richard Ho: I hear you, I think you’ve got the right perspective there. So I’ll be honest with you, a lot of the EDA ML people come and offer us their wares. And I try to give them something very objective, an accessible benchmark, and have them prove to me that we’re going to get the benefits and the results that they say we will.
I tell them, if you can design for me a PCIe controller that meets my compliance suite and you can do it with AI and ML, and you do it faster than us, and you do it better than us, and the area is smaller than ours, and the PPA is there. If you can do that for me, then send me an e-mail. Show it to me, right?
Ian Cutress: With PCIe you have this high speed interface, mixed interface between digital and analog.
Richard Ho: Exactly. It’s a challenging problem. So maybe that’s something for your audience here, that’s kind of the challenge I put to a lot of these companies.
Ian Cutress: It’s a funny story. One company I work with, internally they had four or five versions of the same PCIe controller built by different groups because each only worked with their part.
Richard Ho: It turns out that PCIe, despite being kind of an old protocol, is actually not easy.
Ian Cutress: So in terms of the chip, you called it Jalapeño. Who called it Jalapeño first? Is it going to be a trend. Is the next one going to be Scotch Bonnet or something?
Richard Ho: Could be! So we have a cafeteria in our old building in the Mission district. It’s like a meeting point for everything. And in there, there’s a spice rack, and we love the spice rack, my team loved the spice rack. So we were talking about that, and we ended up calling our team the Hot Peppers. Just like your YouTube channel logo, we were into food as well. We’re kind of foodies ourselves. And then someone suggested, “Hey, we should just go with that theme. And we can just name our devices on that theme.” And then someone said jalapeño. There’s the first one. And we decided.
The other part of it is that’s an internal code name, and for the longest time, we had an external code name. We still do. Typically in these companies, you have an internal code name, an external code name, and you just associate it. When we decided to go public, I went to our communications team. They would ask about when to announce it, what would we call it. I mean, everyone calls hardware like this an XPU. Or other places it’s a TPU here, a GPU there - how many PUs are we going to have? I told them what our internal name is - it reflects the team, it reflects our scrappiness, it reflects how we don’t take it too seriously.
Ian Cutress: The heat!
Richard Ho: The heat, exactly! And then we decided, that’s what we’re going to name it. I think it was actually a good thing, it gives it a name.
Ian Cutress: So in ten years, I will plot all of your chips based on the Scoville scale?
Richard Ho: Which is logarithmic, by the way! It’s no longer Moore’s law. It’s now the Scoville law.
Both laugh.
Ian Cutress: During my PhD, the research group I was on, we made a Scoville heat sensor. At the time, the only way to do that was through having five experts and diluting. So it was a very subjective measure. This nanotube sensor was sold all over to sauce companies. I wasn’t involved, it happened the year before I joined. But it was that research group.
Richard Ho: Everybody has a spice story.
Ian Cutress: In inference, everyone else is talking about partitioning the workload —prefill, speculative decode, then full decode. Separate chips each with their task. Why did you build one chip to rule them all? And one package to bind them?
Richard Ho: The primary thing is that you’ve got to think of it no longer as the chip or the rack. You have to think about it as the entire data center fleet. If you have a partitioning of the data center fleet with a fixed amount of hardware for one part of the workload versus another part of the workload, you have to set the ratio because you’re going to commit to it. You’re going to commit to actual hardware. You’re going to commit your CapEx to it. You’re going to commit your power to it.
Ian Cutress: That only works if you’re only running one model. If you’re running multiple, you could obviously mix and match.
Richard Ho: You can mix and match, right. But even then, the ratios flip around a lot. And in order to make sure that you have minimum regret for how much you’re committing to a particular type, we said we could do it this way.
But the question was, could we do it, actually? So once we figured out that there was a chance that we could, we said maybe that’s a better path because that gives you more optionality and fungibility to the other parts in a data center. You want to be able to move stuff around on different workloads and stuff like that. And if you have a piece of hardware that’s more fungible, that seems like a better bet than not.
Ian Cutress: Do you feel like in design, you might have paid a little bit of a tax to be able to support both and it’s maybe not the most efficient for one or the other?
Richard Ho: It’s a good question. I would say that our architecture is kind of optimal for that. There may be a tax, but it’s not identifiable right now. It may be identifiable when we get into a real deployment, but it’s not identifiable right now.
Ian Cutress: It is interesting, the fact that you’re talking about having a homogeneous data center design versus everybody else in the industry calling for heterogeneous.
Richard Ho: That’s right, it is true. But when we were preparing the Hot Chips talk, we were actually discussing that this is actually perhaps the most controversial thing we’re going to say, because it is bucking the rest of the industry trend to say that we’re going to go in this path. We actually have this device that we now think can actually run the entire gamut of the Pareto, so why not take advantage of it?
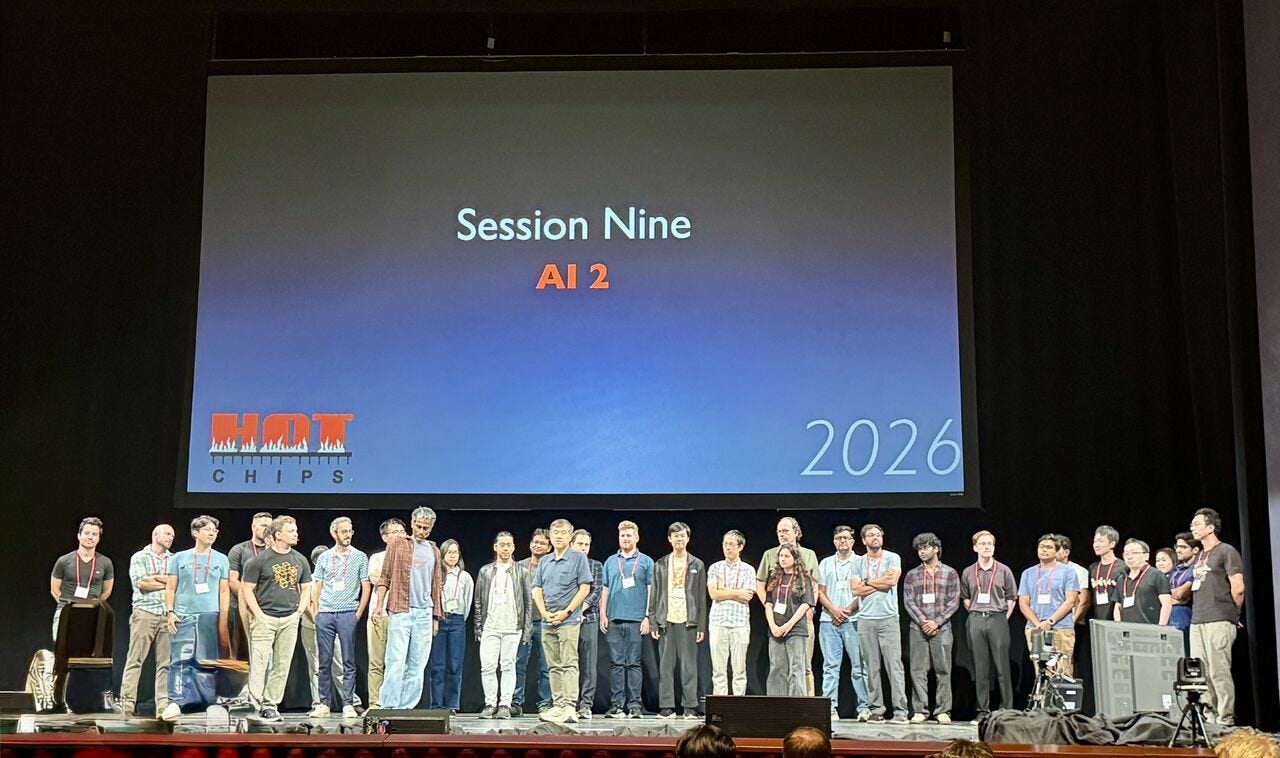
Ian Cutress: I do have one complaint from the Hot Chips talk. You didn’t really talk about the Compute Engine!
Richard Ho: I can’t spill all our secrets!
Ian Cutress: But you did make this sense of data locality being key and we’ve all heard the argument that the less you move data, the more efficient you can be. So can you go into what exactly your architecture does that others don’t?
Richard Ho: So usually with data locality, non-uniform memory access makes the program model more challenging. So the alternative is you have a single shared memory that multiple cores can use. Like in the NVIDIA architecture, you have multiple SMs operating basically on a shared L2 and so any SM can access anyone else’s memory within that uniform memory space.
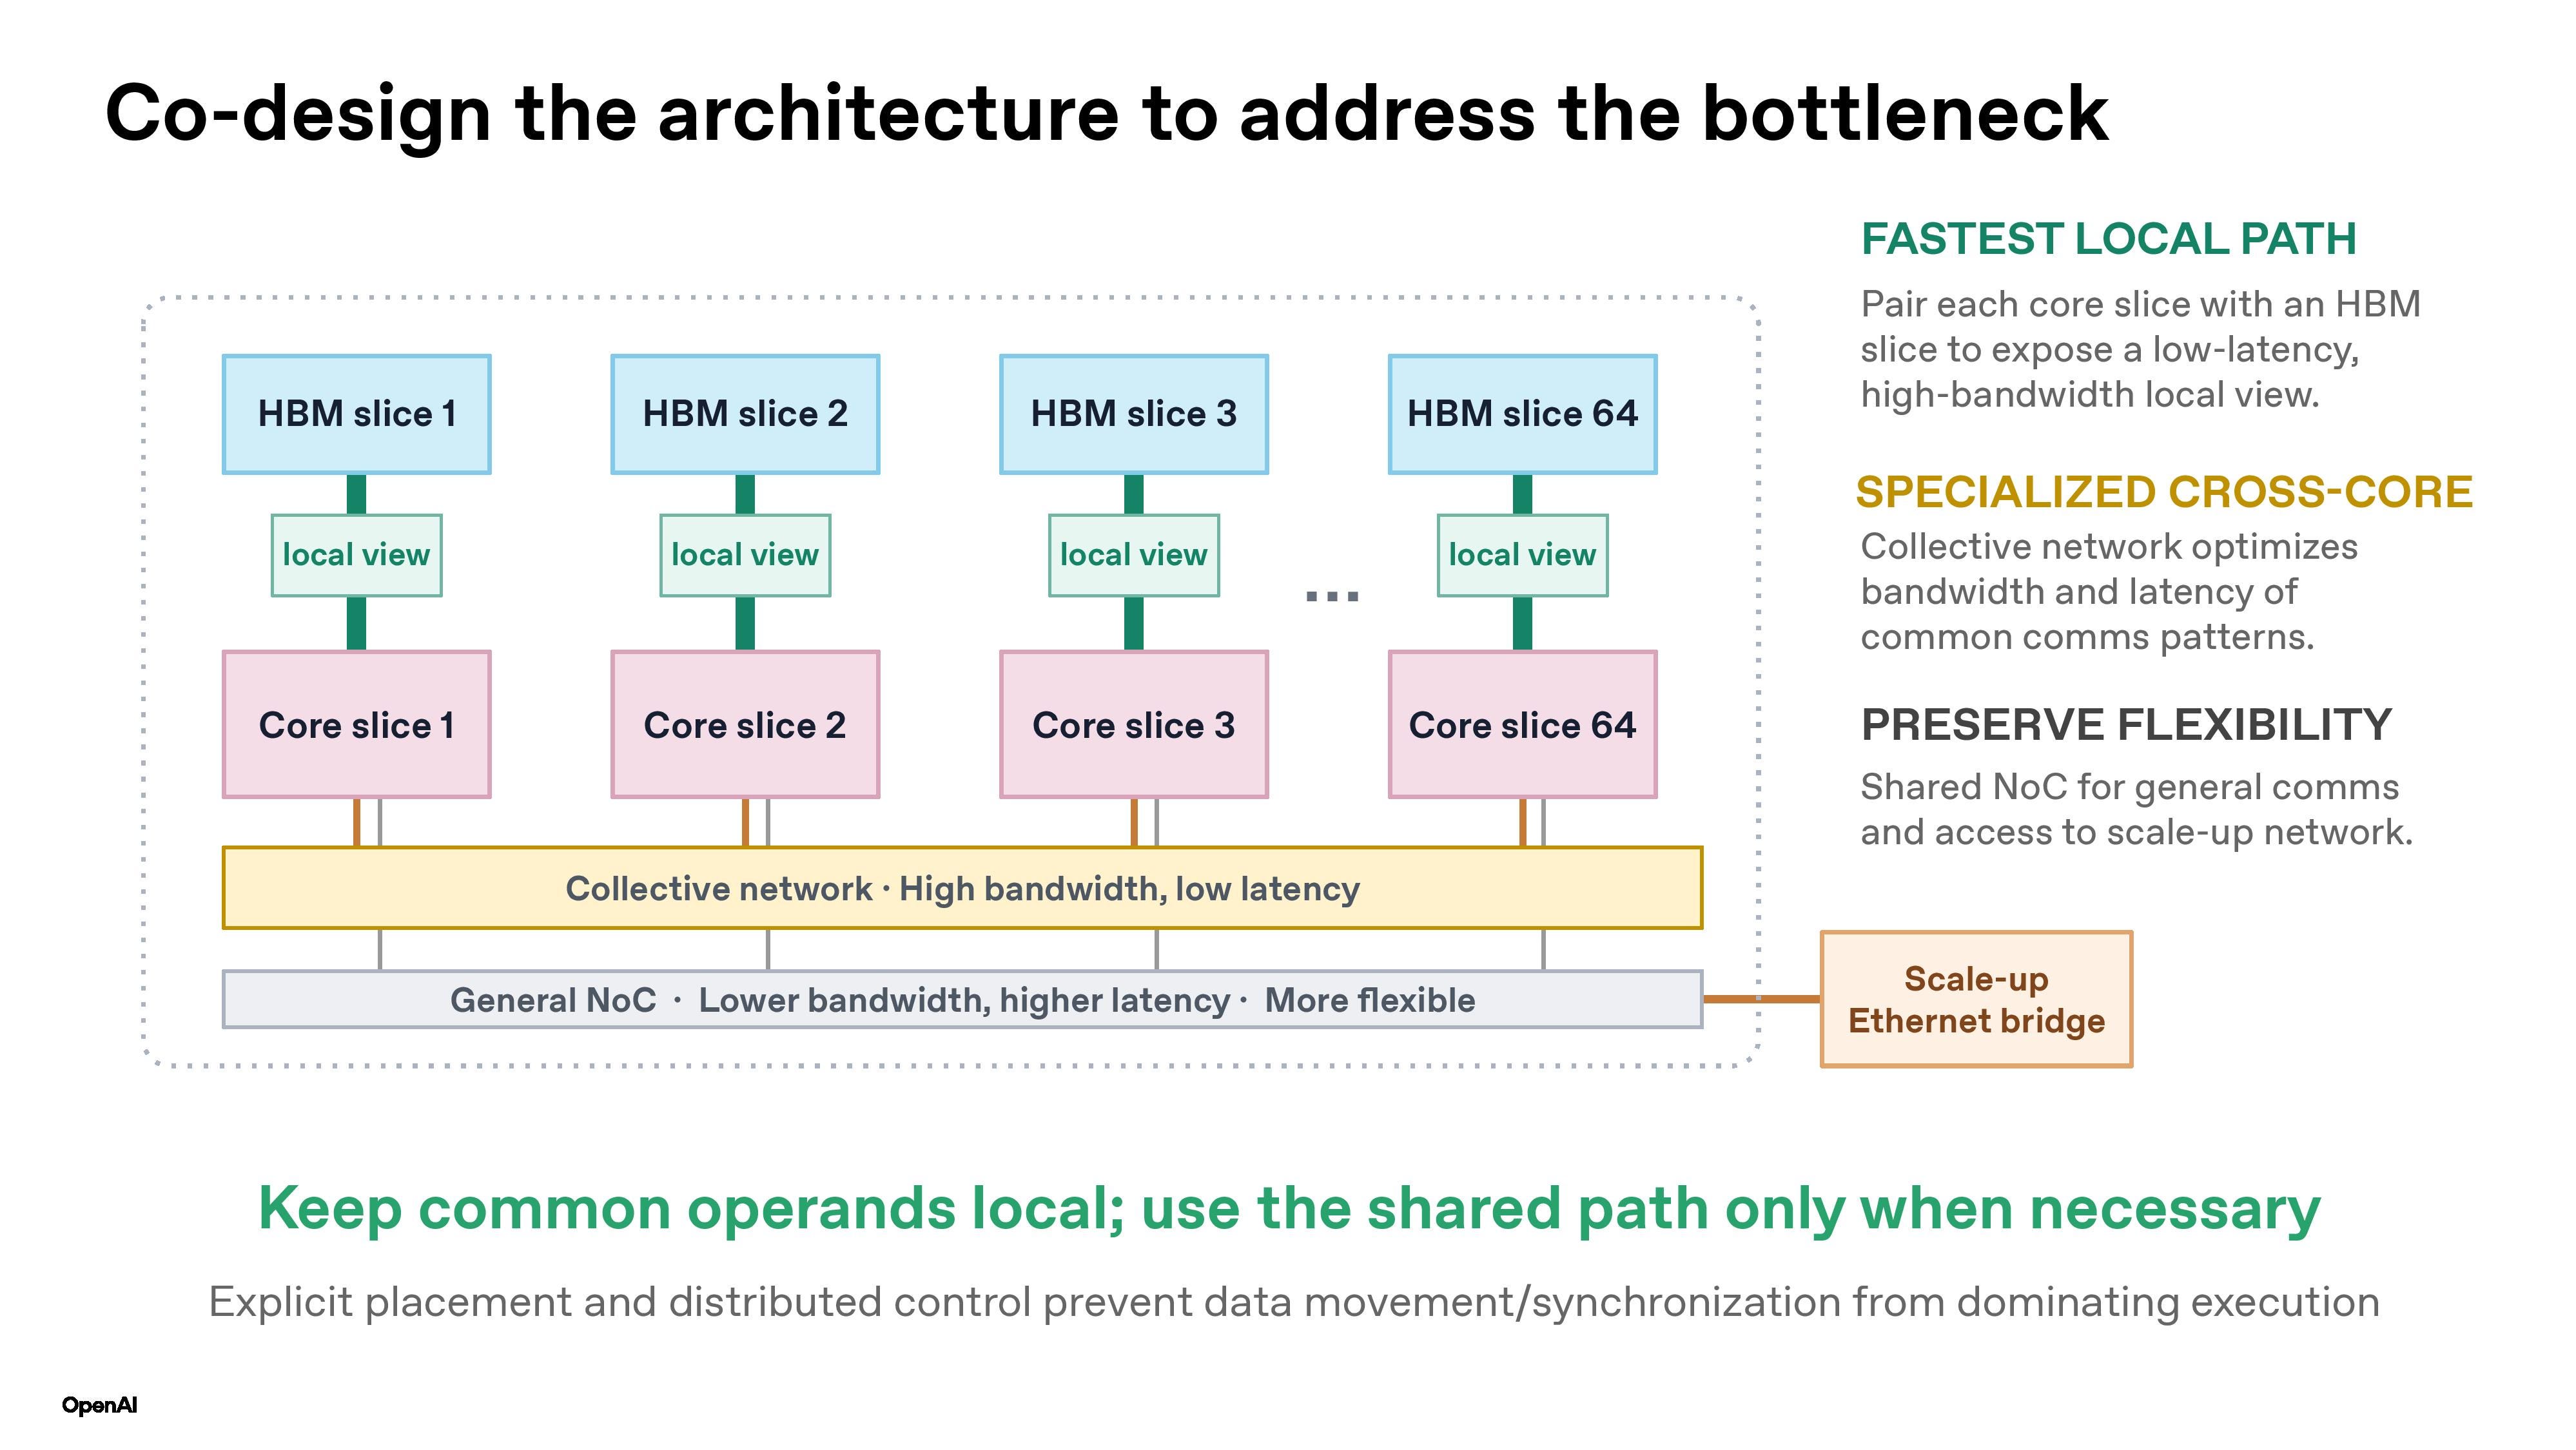
But our architecture has made a very strong bet towards linking HBM banks to cores, that’s the fundamental bet that we’re making. You don’t need to move data around as long as you can operate within that bank and that core, you can just operate within that core. We did talk about that a little bit, we have a ring and stuff like that. But we primarily don’t use the low-bandwidth stuff, we primarily use all our high-bandwidth stuff. So the question was, could you map your workload into the architecture? And that was an open question when we started it.
Through the benchmarking, we basically are showing that yes, you can, because you don’t have to just do it for the models that we were thinking about, which are the OpenAI models, internal models. You can do it for any open source model we’ve found. We’ve not yet found a place where we cannot map it. And of course, the ML is helping to do that as well.
Ian Cutress: But when it comes to enabling things like long context length and KV cache, is that a help or a hindrance?
Richard Ho: So you do have to be very smart about that. And that’s where the kernel...
Ian Cutress: Is this “trust the compiler?”
Richard Ho: Trust the compiler. Trust the optimization kernels to a great extent.
But it is true. There are limits at some very large context lengths, like very, very large context lengths, you may run into some trouble. I think that’s valid. We haven’t seen it ourselves yet. And we don’t know if there’s a solution, there may be a solution there, we just haven’t done that analysis yet. So I’m not going to say this is the panacea for everything, but certainly for everything that we’ve seen up to now, it seems to map out okay.
Ian Cutress: I know your partner Broadcom has spoken about this concept of scale in, just making the package bigger. And Charlie, the president of Broadcom, has shown off the 2028 package. You do rely on Broadcom a lot as a partner. I want to ask, how has that been? You chose them for backend design services over some of the others - what made you go down that route?
Richard Ho: So it’s a couple of things. One is, we do rely on our partners for some of the IP. And so on an accelerator, the SerDes is super important, the chip is really important, the controllers are really important, and Broadcom is very strong with those. But other partners are also very strong with those. There’s also a little bit of the working experience, and obviously Broadcom and my team have a pretty long history.
We’ve been working with them in previous chips. For some of the people, we’ve been working with them for a decade, so we know them. But I think the other part of it is also the volume. Sam wanted a lot of volume, and that’s why we’re talking to TSMC, talking to SK hynix and Samsung.
Broadcom is one of the volume players. You need to have someone who has access to the wafers and the memory. Because if you’re a startup team in a software company, are you going to get those wafers at TSMC? Not off the bat. So you have a strong partner to go get all that for you.
Ian Cutress: They’ve also managed the packaging supply chain as well, because that’s obviously quite pinched right now.
Richard Ho: It is quite pinched, yeah. So I think, again, there’s a lot of experience in their team. And it’s a great team, we love them, they’re a strong partner for what we do. They have strengths, we have strengths. I think that’s what you look for in a good partnership, is to feed off each other’s strengths.
Ian Cutress: One of the comments I’ve seen is that Broadcom aren’t necessarily the cheapest in the industry. But also, the way that TSMC works, and the way that the packaging companies work, is if you pay more, you will be put further in front of the line.
Richard Ho: Only for a limited volume, though. You can’t get a huge volume to the front of the line, I don’t think.
Ian Cutress: But in that sense, it kind of goes back to my blank check question. How much of the time to market do you think you put on the fact that - and maybe you can tell me I’m wrong - that maybe OpenAI paid a bit more to get their chip earlier than perhaps others in the queue?
Richard Ho: So that’s not the part that we were trying to accelerate. The part that we accelerated was the design to get to a chip, to bring it up. That part is kind of independent of the other part. Now we’re going into volume ramp, so now we’re trying to get production. So yes, in that aspect, there may be some things going on there.
Ian Cutress: Or I guess getting the first A0 helps, but then B0 is volume. So you’ve got to put the values in.
Richard Ho: You’ve got to think about those in different phases and different ways a little bit.
Ian Cutress: On the architecture, what aspects of the design do you think people will copy?
Richard Ho: Well, I think I’ve been pretty explicit that NUMA is the way to go, so I suspect that you’ll see more of that. I wouldn’t be surprised to see even the GPU people going down this path.
Ian Cutress: So more fractional memory, cached hierarchy.
Richard Ho: I think so. I think that for years in the research, people were talking about computing in memory or processing in memory, it was always difficult to implement and difficult to map the software to it. We’ve shown a step along that way, and I think that is definitely a path we expect people will follow.
Ian Cutress: It’s private caches all the way down!
Richard Ho: Yeah, exactly! So we anticipate that, we’ve anticipated that. And we’ve made this like, are we going to keep this to ourselves? Are we going to tell the world? We decided to tell the world. Why? Because we still need GPUs, and we want GPUs to get better.
Ian Cutress: Come and have a go if you think you’re better than us?
Richard Ho: I mean, that’s interesting, right?
Ian Cutress: I do wonder what was in Jensen’s brain when you showed him the Pareto curve against Blackwell, you know what I mean?
Richard Ho: I think he’s a very competitive person in a positive way.
Ian Cutress: But you’re also one of his biggest customers.
Richard Ho: We’re also one of his biggest customers. And I think the way I see it is that quality results beget more quality results. So we’re going to push them hard because that’s what I think we can do. And we think and we believe that they will respond and push us hard. And what does that mean? It should mean that AI infrastructure gets better and cheaper.
Ian Cutress: So in terms of quality results, you decided to use InferenceX. There was a comment about why you would use a third party benchmark and numbers, and why that one in particular?
Richard Ho: Because we found that one is end-to-end. I think third party should be pretty clear, we didn’t want there to be any questions as to how we did the benchmarking. We didn’t want people to question our numbers. So we used a third party one with defined metrics, and people can just go do it.
Ian Cutress: Even though those benchmark models that won’t actually run on the chips in production?
Richard Ho: Even though it’s actually - yes. But the whole point was, we wanted the numbers that we presented to be unassailable. We used a published methodology that someone else set, using models that are open source so anyone can access them. The results that we have should be unassailable from a methodology viewpoint, that’s what we wanted to do there.
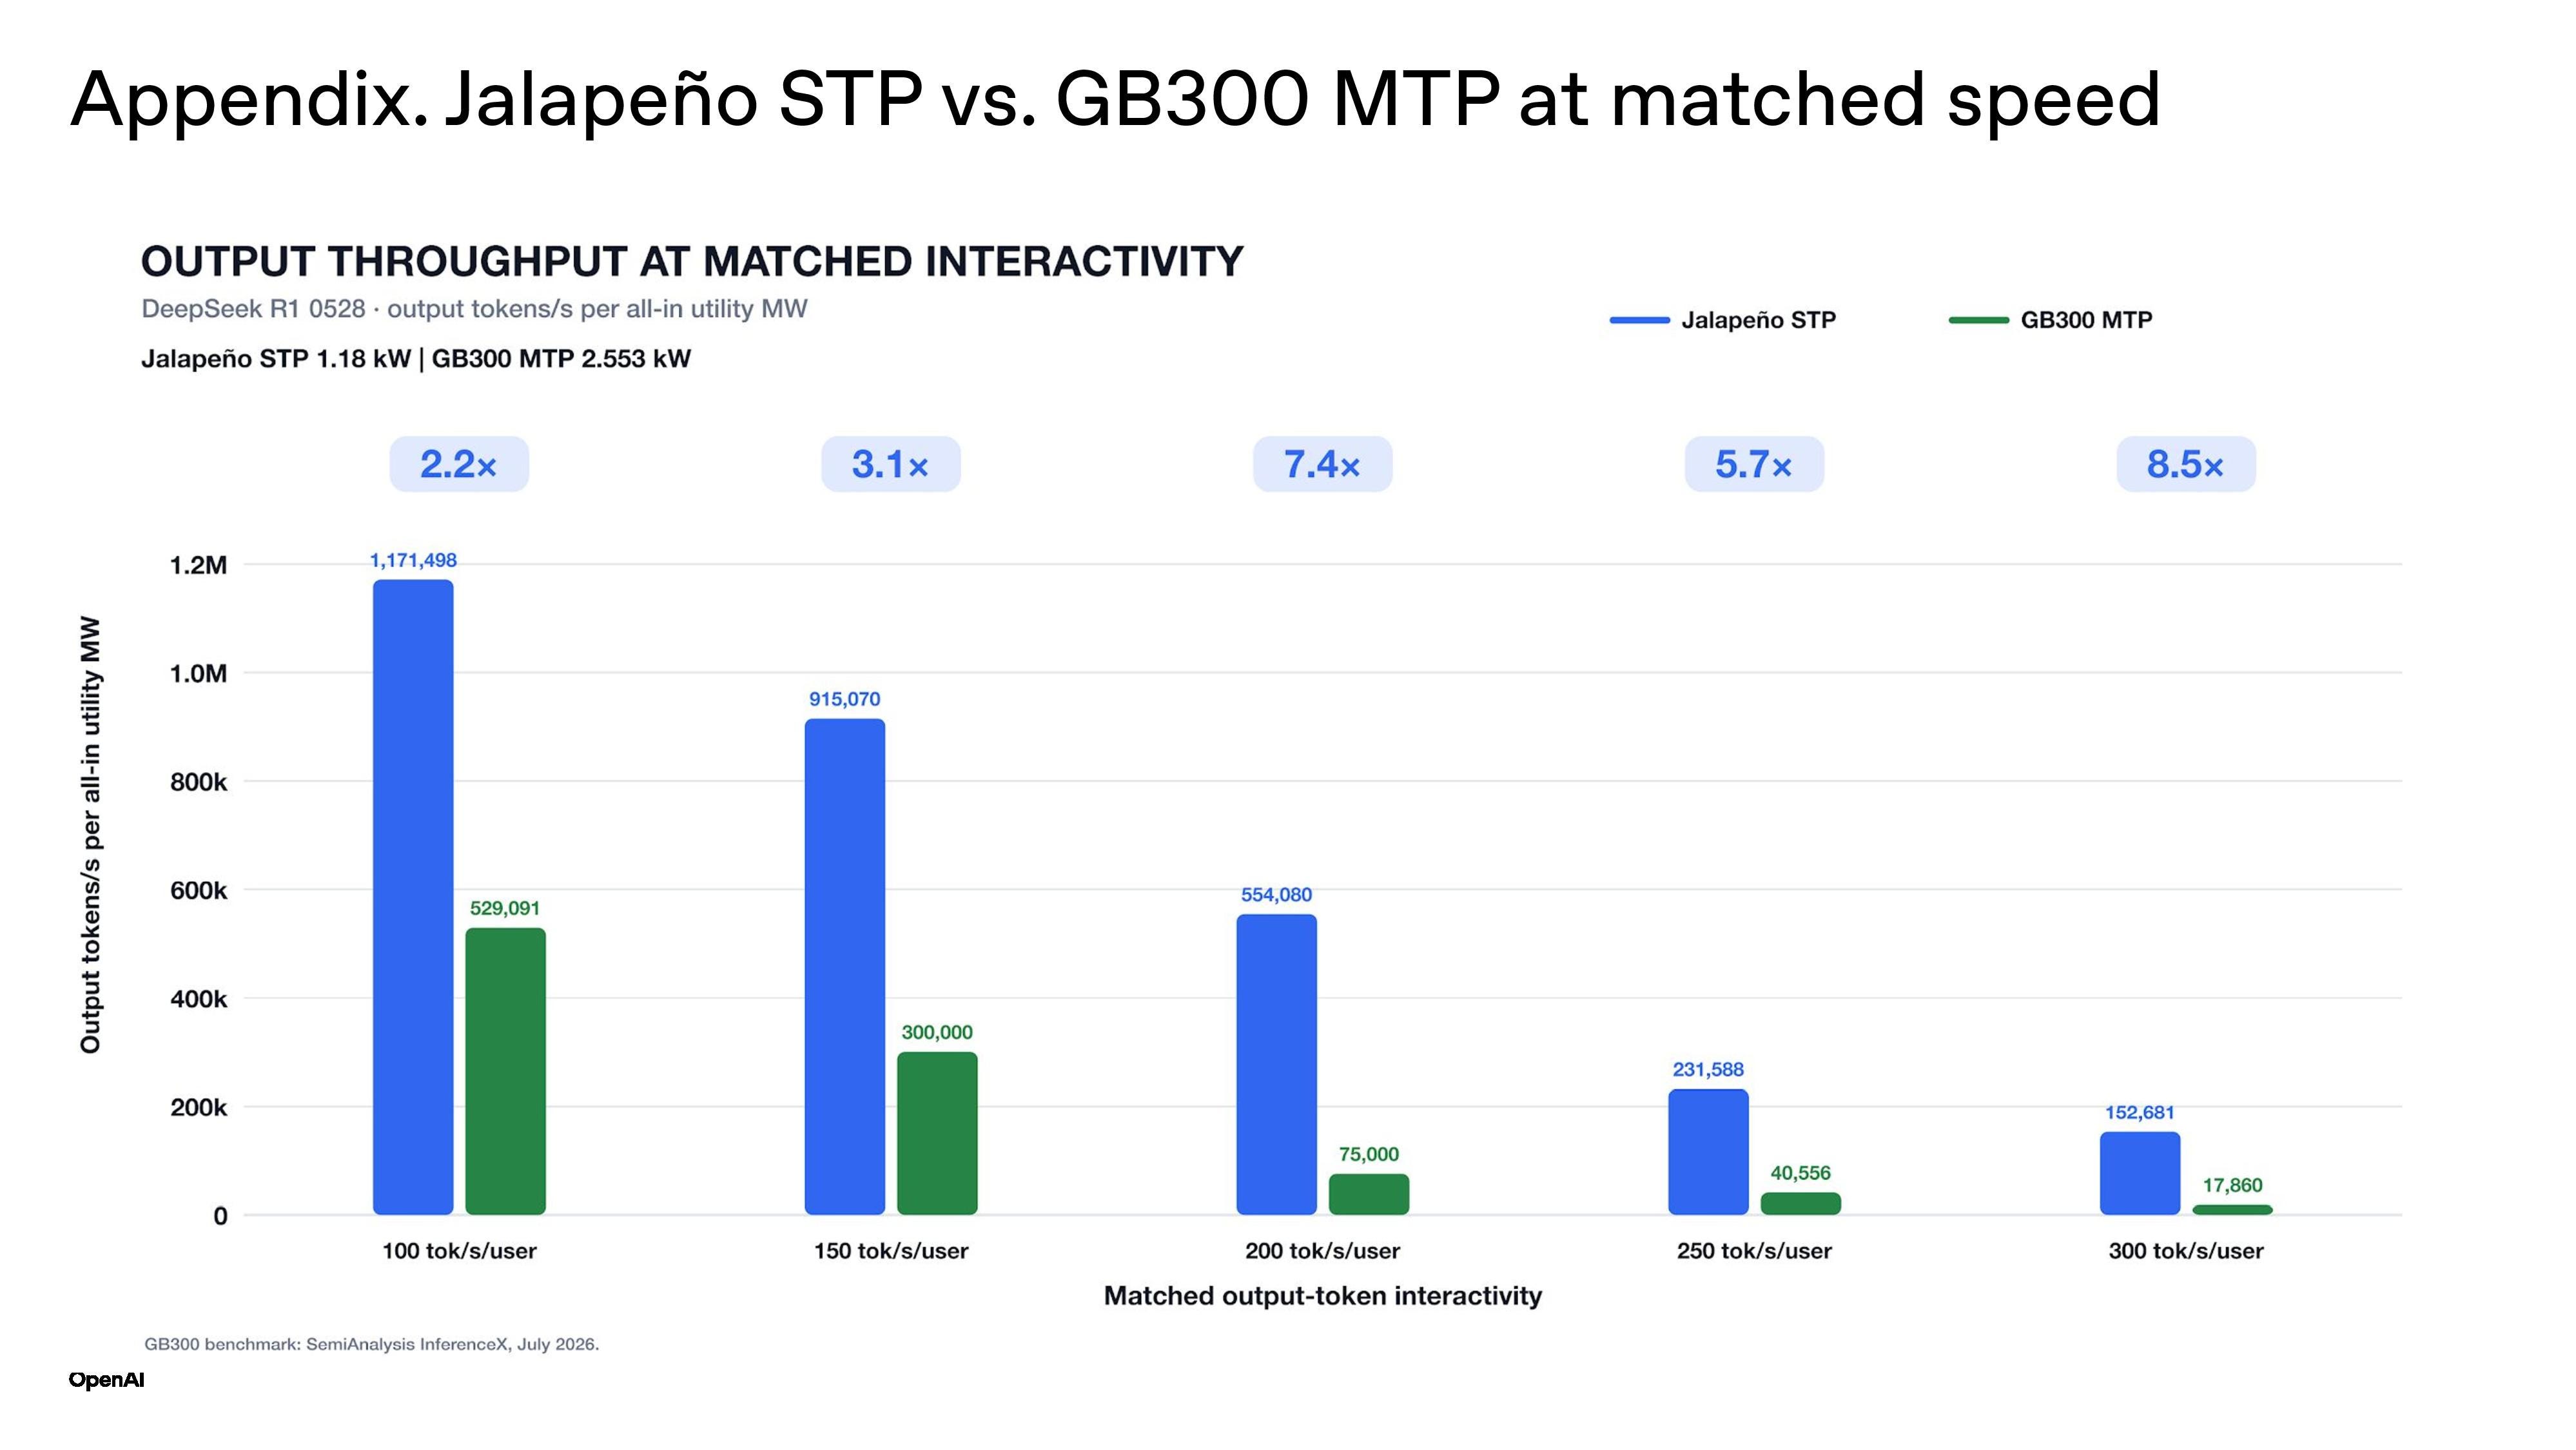
Ian Cutress: You also showed single token prediction and multi-token prediction results. What is the reality actually in production? I’ve got to assume it’s MTP.
Richard Ho: It is MTP. Again, all the way down. All the way there, yeah. Let me explain why we showed some but not all the numbers.
So we sprinted on this. We got the chip back around mid-May, and at that time, we weren’t even sure we were going to do an open Hot Chips talk.
Ian Cutress: You guys came in late. I spoke with the committee about this. If you were any later, Etched would have taken it.
Richard Ho: We came in very late, yeah. We really appreciate the committee. They actually had a slot and we said we’re not sure yet. We asked how late can we confirm with them.
But they gave us a slot, and at that point, we did a sprint. And to do the sprint, we asked what the right way to do it was. We chose InferenceX. We chose three models because we want to show a range of different things, different sizes and stuff. But if you did speculative decoding, you had to do a draft model of that, and we didn’t have that for the open source models. Do we have time to do that? No, and so we asked anyway about how our STP numbers look like versus the published MTP numbers.
Then we set a goal. Can our STP beat the MTP numbers? That would be shocking if we could do it. We set the kernel optimization team on it and they really sprinted hard, and they were so happy. We were so happy. I was so happy when we showed our STP numbers beating the published MTP numbers.
Ian Cutress: Do you think then, given that that was a sprint and perhaps not the fullest of data sets, is there an inkling to eventually have a bigger data set in the future published? Technically don’t need to promote it because only you’re using it internally - nobody else is using it.
Richard Ho: I think benchmarking is important to understand relative performance. Because there’s a lot of marketing claims in hardware. I think that one of the things is that it is important to have good benchmarks so that everyone knows exactly what we’re getting. The flip side of that is that we did it for the purpose of Hot Chips and getting this announcement done and having people understand what we’re doing.
The team has already flipped over to do production in our work. So we may not be doing a lot more of this. We may do AgentX when we get a chance, but we probably won’t be spending a lot of time optimizing the results.
Then I think the flip side is that if you have good benchmarks that actually represent workloads, then you can actually drive the architecture work. Because then if people are actually trying to optimize the benchmark, they can optimize the right way. So that’s the other side of it. You can use this as a tool to shape what the hardware does.
Ian Cutress: But back in the CPU days, we used to get compilers doing specific optimization for different tests! Is there a benchmark the industry doesn’t have that you would want to see?
Richard Ho: Well, I think the new agentic stuff is going to be important. I think we need to do more on that to get a representation of all the different parts of the workload. I think diffusion models, the inference, the image generation, the multimodal stuff.
Ian Cutress: Some of those are relegated to tool calls now.
Richard Ho: They are, yeah. I think I need to spend more time thinking about that.
Ian Cutress: How often will you get external people coming in and evaluating the silicon, either privately or publicly?
Richard Ho: We actually invited the SemiAnalysis people in to evaluate it. That was really for the purpose of, again, making sure that the results were objective and unassailable from a methodology viewpoint. In general, we work with our partners, so our CSP partners, everyone who works with us.
Ian Cutress: You do a POC for them?
Richard Ho: They get access to the infrastructure, the software stack. They get access to the hardware early and stuff like that. Anyone we’re going to deploy with has access to it early, because there’s a lot in the data center, more than just the chip and the kernels. There’s all the management layers, there’s a part that kind of wanders everything and tells you when things are failing, and all that stuff has to be integrated.
Ian Cutress: What about on the CPU side? Because one could predict a future environment where OpenAI makes its own CPU!
(Both laugh.)
Ian Cutress: Given the fact that everybody’s talking about agentic, but you guys have obviously been doing it for a couple of years at this point, and there’s an argument, x86 or Arm. Where exactly do you sit or have any opinions on that regard?
Richard Ho: So I think that if we had some insight into how a better CPU could be designed, we would definitely do something about it. But that’s not something that we’ve spent a lot of time thinking about yet. It’s a relatively new kind of thing. I think we have very strong CPU partners. So there’s a good likelihood that instead of us doing it, we’re going to push our partners in certain directions.
Again, it’s this focus thing. We need to focus on where the best bang for the effort and the buck is. And right now, it is on the workload acceleration.
Ian Cutress: There are reports coming out about exactly how much time is in the models versus the tools. I know my workload is getting pretty tool-heavy at this point.
Richard Ho: Yeah, I agree with that, so I think it’s something we need to look at. We haven’t looked at that too hard.
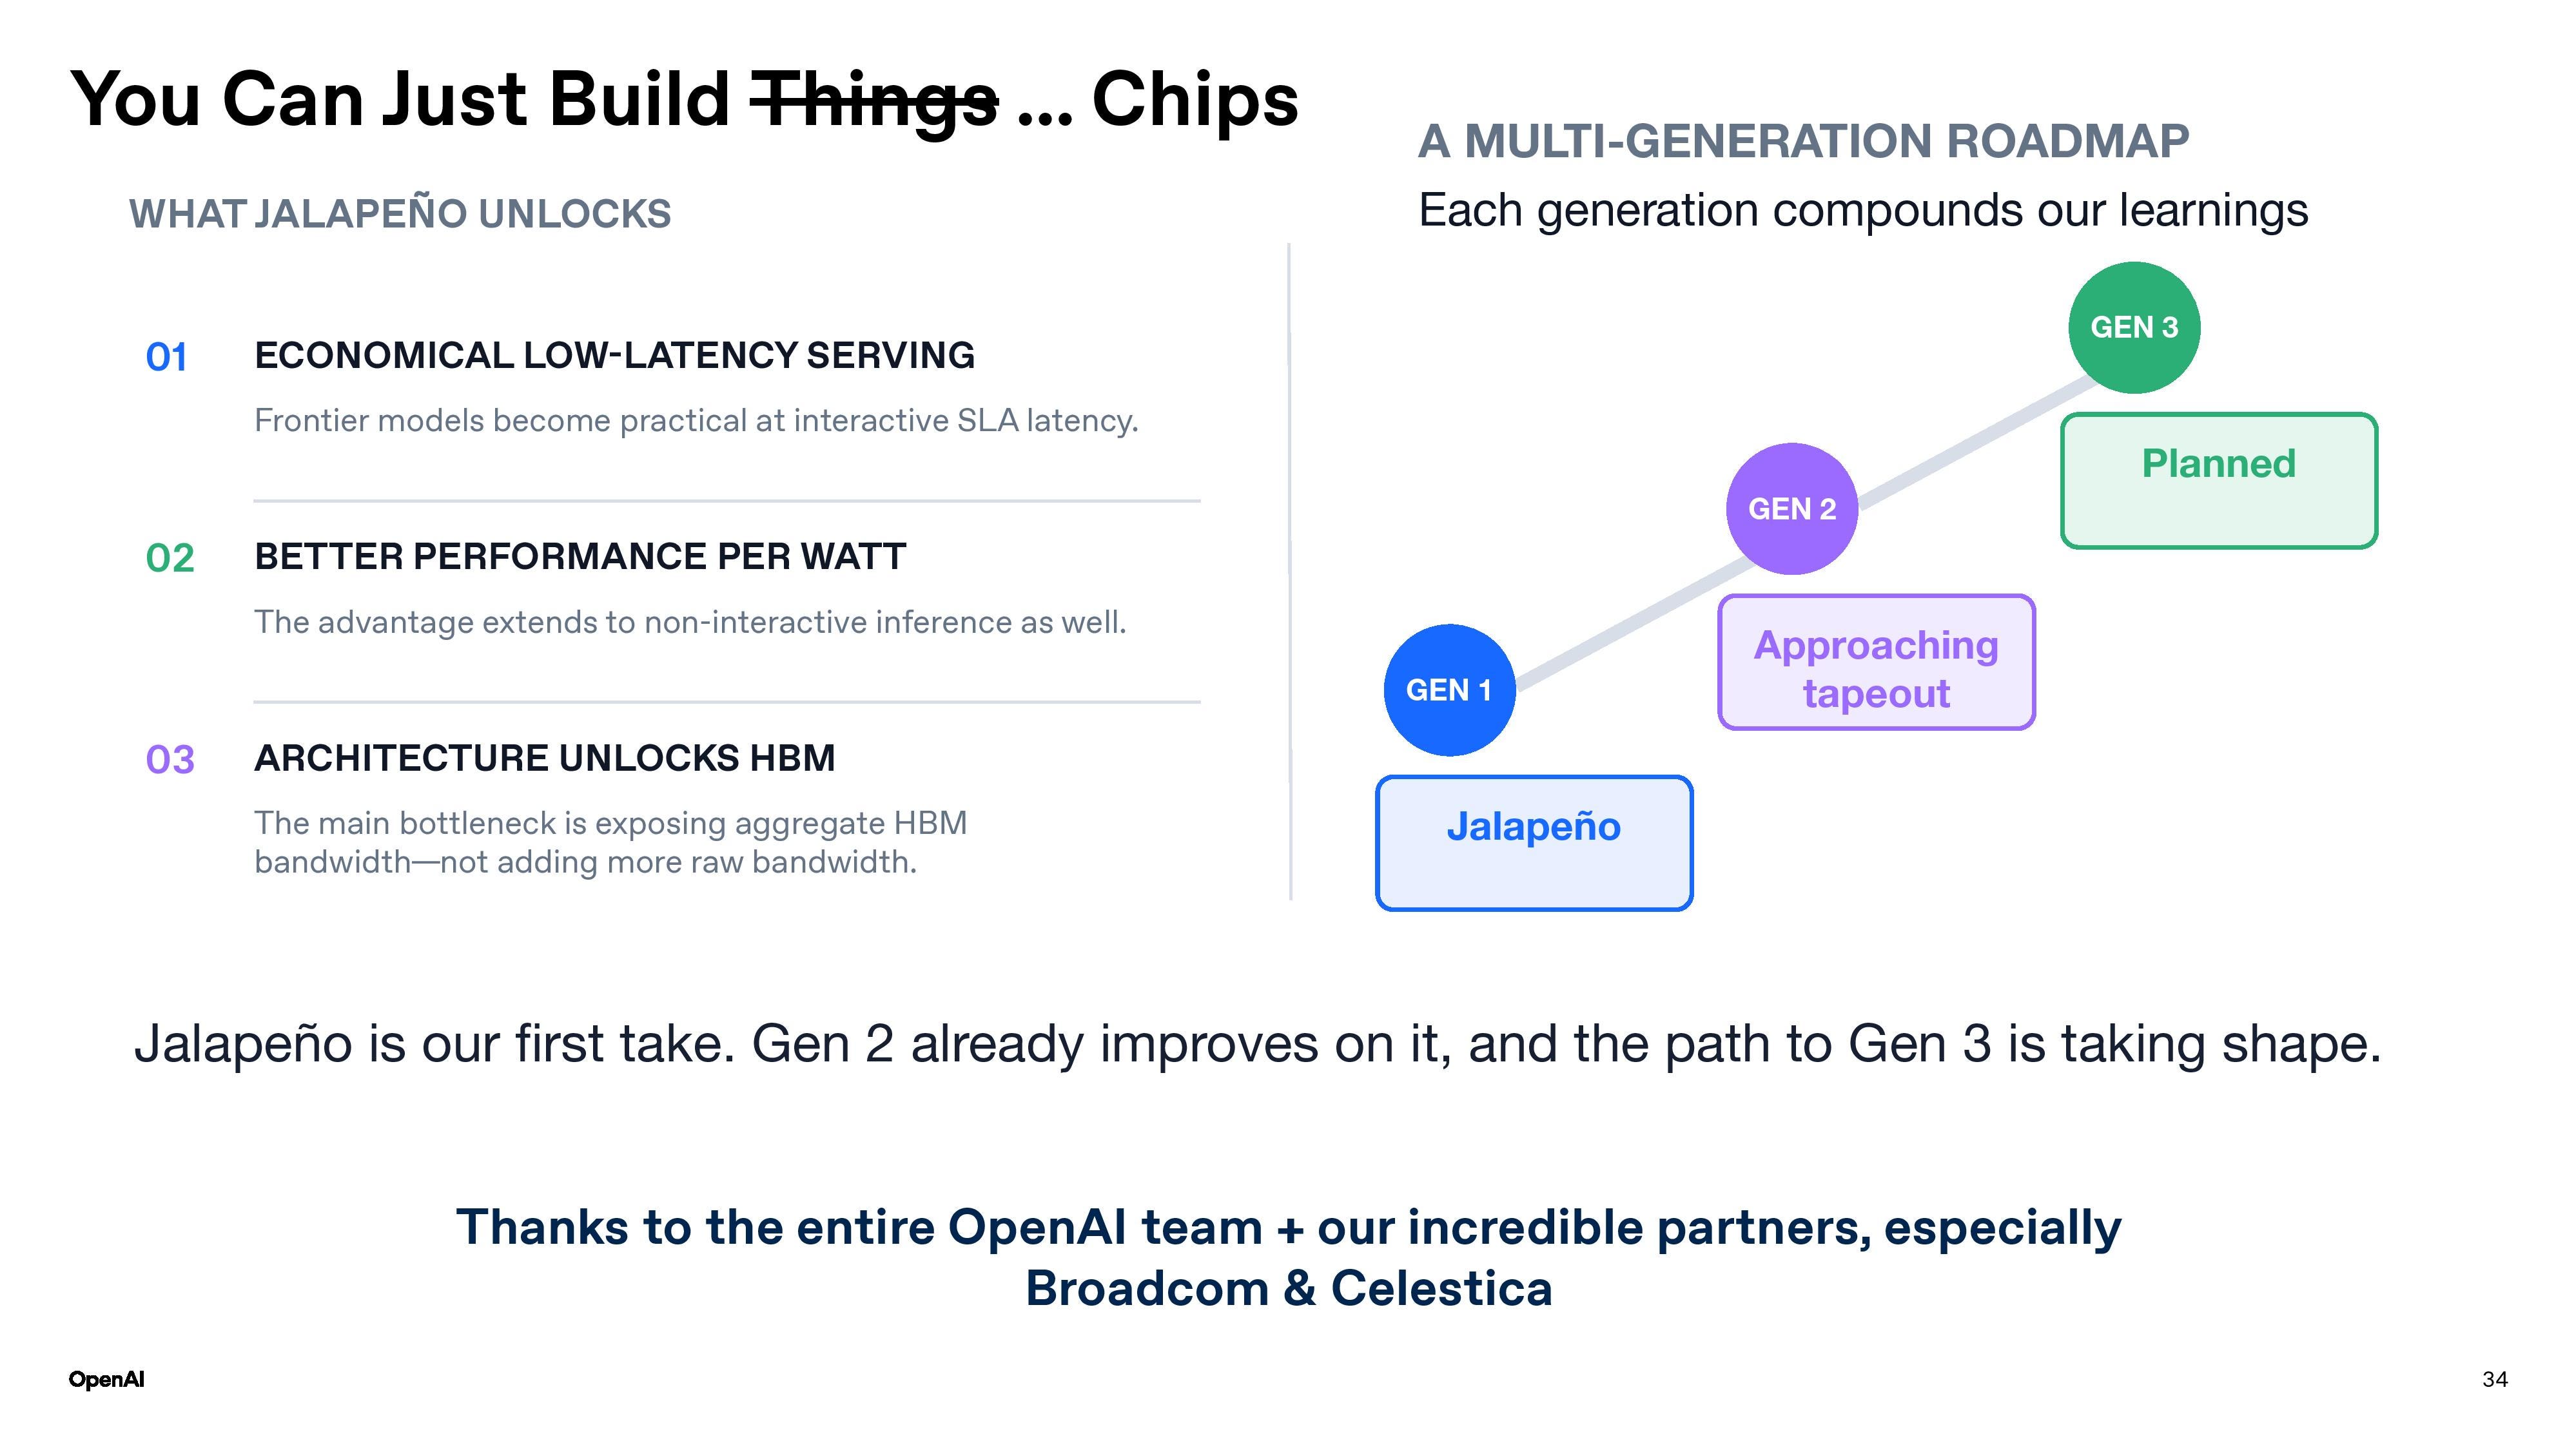
Ian Cutress: At Hot Chips, you also announced the roadmap. This sort of like the Gen 1, the Gen 2, the Gen 3. I know you don’t want to announce anything, but should we think of these as fundamentally updated architectures or iterations on the same idea?
Richard Ho: There’s no one answer to that one. There will be some iteration.
Ian Cutress: Because I remember you talking about low-hanging fruit.
Richard Ho: So Jalapeño was definitely low-hanging fruit, and there’s probably more benefit you can obtain with using that architecture, and we intend to gather that. But I think as we go forward in the roadmap, we may actually bring in additional architectural innovations that may require a little bit more work to analyze and figure out if the software can handle it.
Ian Cutress: How many of those architectural innovations, again, at a high level, are derived from how the models are evolving internally versus just simply accelerating the existing ones?
Richard Ho: Definitely a lot of it is dealing with what we think is coming. And so that’s the interesting thing, which is asking how often the models actually change.
The way you think about it is that the researchers are constantly looking at new ideas, they’re constantly thinking about new things, they’re trying experiments. And what’s happening is that they try to experiment, they actually run data, they actually try to gather data. Is this positive, negative? You’re kind of almost doing an A-B test. So we’re looking at that.
The time it takes from someone to have an idea, to gather the data, to someone saying, we should put a feature in, it is actually not that fast. It actually takes months, right? It’s enough time for us to look at it and see whether it’s promising, if we should evaluate, and if we could support or optimize it in someway for the achitecture. So I think a lot of it is going to be fed by exactly what’s going to happen with the future models.
Ian Cutress: Before AI, hardware cycles were typically three or four years. Now we’re talking about data centers keeping AI chips for seven? What’s the attitude inside OpenAI for keeping that hardware running for a long time, and how do you approach your chip design as a result of that?
Richard Ho: That’s a really good question. I think it’s something that’s valid because of the amount of chips that are going in at every generation. Huge amounts, and none of them are being decommissioned. Not yet, anyway.
So I think the way you think about it is that there’s multiple tiers of customer expectations. Like the top tier customers are expecting the fastest, most performant models coming back, like large token budgets and stuff like that. You could afford to have your very latest hardware serving that tier.
And then you get all the way down to the kind of almost free tier, right? And the free tier, you know, as Sam talks about it, it should almost be like a utility. It should almost be like a basic given right, right?
Ian Cutress: So the analogy I have is, do you remember when we used to pay per minute for phone calls? Eventually the technology got so good, we got them for free with a monthly subscription. When are we going to get there with, say, a 1 billion parameter model, a 3 billion parameter model?
Richard Ho: I don’t know when we get there, but that’s the path we’re on, right? And I think that’s where the older hardware ends up, is that you can still serve it and it’s good. And in many cases, the hardware has already been depreciated on the balance sheet and stuff like that. So you can have a lot of it. It’s just using power. At some point, yeah, you want to get rid of it because it uses too much power, right?
Ian Cutress: I kind of want that free token layer to hit before we hit the power limits. But then we might get Jevon’s Paradox coming and it just blows up.
Richard Ho: Yeah, but that’s the way I think about it. Right now, there’s so much appetite for more tokens and more compute and more intelligence, I don’t even know when we’ll start taking some out of it. Although some of the older GPUs are starting to come out of the fleet.
Ian Cutress: As you look towards the future hardware, what do you need from your memory vendor partners? It’s all very well saying capacity, bandwidth, power. What are you asking from them?
Richard Ho: The memory partners, they’re talking to all the customers, and they’re talking to us. We’re talking to startup companies, we’re talking to Nvidia and Dell. And in many ways, where memory is going is different from the recent past. The recent past has been HBM2, 3, 3E, 4.
Ian Cutress: Well, HBM was a commodity before, and now it’s no longer a commodity with custom.
Richard Ho: I think custom is where it’s going to head a little bit, is that the architecture. I think this is valid across not only memory, but across the networking as well - is that you no longer think about these things in isolation. You have to think about it in the totality of the system. What do you need from the system? And what does the memory need to provide? What’s the networking need to provide? And you need to design it together.
Ian Cutress: So instead of speaking to the memory vendors, realistically you’re speaking to Broadcom because they’re the ones that are doing all those interfaces?
Richard Ho: They’re doing a lot of it. But we’re speaking directly to the memory vendors, because we’re doing the higher level design, so we are formulating the system. We’re formulating what needs to be there, what to balance, what even the physical layout is. Yes, Charlie (Broadcom) has this big thing, but then he’s basically coming to us and saying, how would you use it? And we have to figure out, can we use it? Is it the right thing? What modifications do we want? And it’s equally true for the memory. When you talk about advanced memory, you’re going to stack the memory over. What are you going to do there? And if you do that, how? Why? What would you do? What do you need? How many layers? All this stuff, right?
So it starts to get very interesting. One thing that I’ve said a few times, that when John Hennessy and Dave Patterson won the Turing Award in 2017, in their award speech they called it the Golden Age of Architecture. This is the age of custom ML accelerators and other accelerators. We are, I think, now in the Golden Age of packaging.
(Both laugh.)
Richard Ho: Right? It’s about system on wafers, about system in panel, and full wafer scale. How do you integrate all that? Panels and optics. It’s no longer about the individual computer, it’s about how you pull all these components together in an efficient way.
Ian Cutress: As we look to the future, where exactly do you think the limit is in the ecosystem? Because everybody talks about power, memory, packaging, people, supply chain.
Richard Ho: I think right now the limitation is on people’s ability to understand how big this thing is going to get, because it makes investment decisions harder at the scale that’s needed to keep up with the demand.
Ian Cutress: Is that a personal statement? Or is it a government one?
Richard Ho: I think it’s a supply chain statement. And I think it’s about not only government, but also about individual companies, CEOs, controllers, people who need to make these investments. They’ve seen these cycles in semiconductor and energy and internet and other things where people overinvested, and it kind of holds them back. I think that we’re in this interesting phase where it’s exponential because we’re heading to a new baseline and people are still operating on the old baseline, and so they don’t realize how much needs to get invested to get to that new baseline. So they’re hesitating and not really making the bets big enough, I think.
Ian Cutress: I remember Pat Gelsinger saying the only way Intel survives is betting the whole company every generation. These companies never had to, and now you’re saying that they kind of have to?
Richard Ho: They might have to, yeah. I think that’s the thing I’m seeing is that, again, because of the scale of everything, the almost 130 billion dollar company, you have to have the guts and the confidence to be able to make those very big bets.
Ian Cutress: Do you spend much time thinking about non-Von Neumann architectures at all?
Richard Ho: Yeah, we look at everything. I spend a lot of time looking at all types of things, analog compute, even looking at biological compute in some cases. We look at everything. My team actually has a set of people whose job it is to keep evaluating the crazy ideas, because you don’t want the crazy idea to get away.
Ian Cutress: Now we touched upon this at the beginning about your work at D.E. Shaw and the Anton supercomputer. It was a molecular dynamics accelerator at the time, offering up to 100x the best supercomputers. But even then, that team has now announced they’re no longer making custom chips - they’ll just buy GPUs and use AI. So does AI beat specialized silicon going forward?
Richard Ho: Good question. Yeah, it is true. That team was building these Anton supercomputers and doing a custom ASIC, and then AlphaFold came along. It’s interesting that the cofounders, the two Nobel Prize winners, one of them actually was from the Shaw team. John Jumper came from D.E. Shaw Research. So it’s possible. But then if you think about it, what is the hardware? When people say custom silicon, it’s custom only because it’s not off the shelf, but it could easily be off the shelf.
Ian Cutress: Well, this is why I say Anton, right? It’s one example of a team having enough finances to go build for a very specific workload and not be like a true ASIC, like a Bitcoin miner. And the fact that even that’s now gone almost to AI, right?
Richard Ho: So think about it this way - do you consider GPU as kind of the general purpose thing? Or do you consider CPU? Because the GPU started off as a kind of custom accelerator off the side of a CPU. Now it’s kind of the workhorse of AI. What if one of these is the new kind of inference accelerator that becomes off the shelf for everybody?
Ian Cutress: Well, then we get back to having a heterogeneous infrastructure, not a homogeneous infrastructure, right?
Richard Ho: It is a different thing, though. I think having a heterogeneous infrastructure is probably a good thing. I think where we’re worried a little bit is having it per workload, basically, like saying this cluster is going to only do this thing. That’s a little bit of a nuanced distinction there, but that’s kind of the thing. Do I think that we’re going to continue having CPUs in the fleet? Absolutely. Are we going to have GPUs in the fleet? Absolutely. Are we going to have these inferences in the fleet? I think so.
Ian Cutress: Let’s look five years in the future. What would make you consider your work here a success?
Richard Ho: I think the bottom line is, were we able to reduce the cost of infrastructure so that we could provide more intelligence to users at a lower cost? If we were able to do that and basically do that through this full stack optimization that we’re trying to do, then I believe that’s a success. No matter what the path is to get to there, that’s the ultimate goal of why we’re here.
Ian Cutress: And you’re defining that as with partners rather than alone? Whatever works?
Richard Ho: Whatever works, right? I think the mission is pretty clear and I think everyone who works on the team is very aligned with the mission, which is providing intelligence for the benefit of all humanity. So for us, what that translates to, is making it cheap enough and performant enough and pervasive enough. And pervasive enough is not just in the data center department, it’s in the edge as well, and so within the company, we know that we’re doing that stuff as well. So I think that’s gonna be the most important thing.
Ian Cutress: If I was to interview Sam Altman, what question do you think I should ask him? What do you think the audience wants to know from him about what you guys are doing?
Richard Ho: I think it’s about how are we gonna get to pervasive intelligence. I’m working on one part of it, but Sam’s thinking about the whole thing. I think that that is part of what his bet is in OpenAI. He’s acquired teams and there’s other stuff going on throughout that may not be talked about that much in the press yet, but we’re looking at intelligence as being pervasive and being available to everyone everywhere. And so what does that mean? That’s the interesting thing. And the data center is part of it, but it’s not the whole part.
Ian Cutress: Thank you so much.
Richard Ho: Pleasure.
The roofline number stood out: an attention kernel going from under 1% to nearly 90% in about forty hours. If model-assisted kernel tuning holds up across workloads, the software moat around incumbent accelerators thins faster than most people model. Curious whether 216 GiB of HBM4 per part makes memory supply the binding constraint on scaling it.
The fleet-level argument for one accelerator was the strongest part. Did Richard quantify how much utilization improves when prefill and decode ratios shift, compared with committing capacity to separate chips?